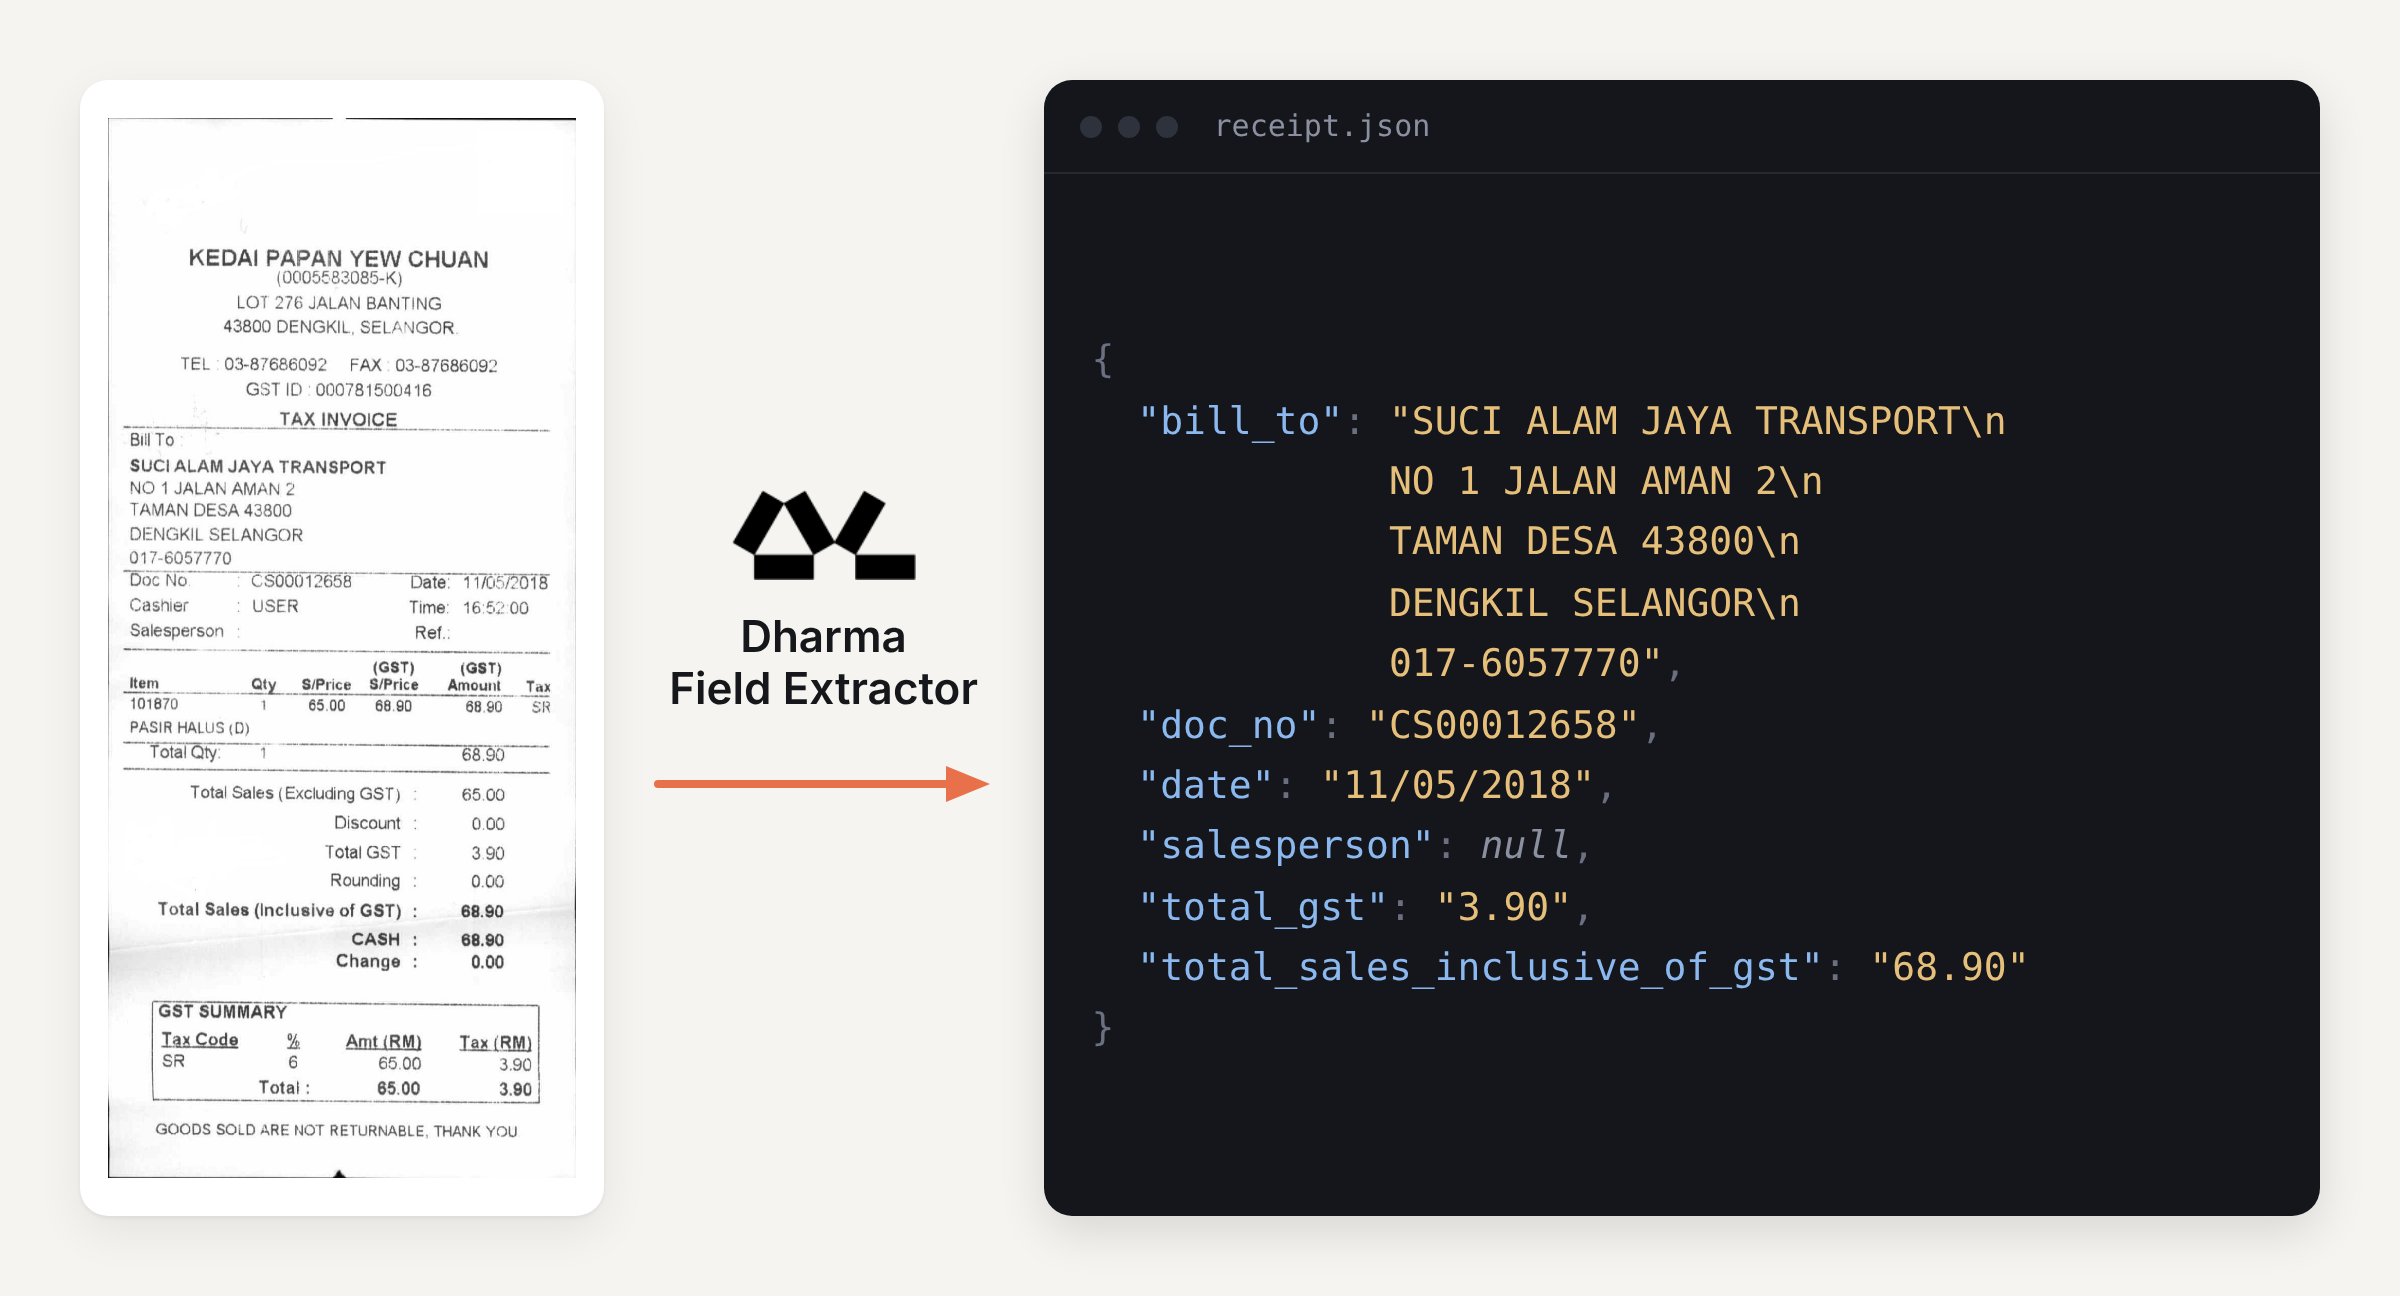
Dharma Field Extractor is a 2B parameter model that takes a document image and specific field schema, then returns structured JSON. It outperforms frontier LLMs by up to 9.3 points on field-level F1 benchmarks while costing up to 147 times less than general-purpose APIs.
It handles multi-domain documents without per-type fine-tuning, making it useful for high-volume invoice or ID parsing where cost matters. The catch is that you must manage the initial OCR pipeline yourself and ensure your input images are clean, as the model relies on a separate specialized base for text recognition.
more: https://huggingface.co/blog/Dharma-AI/dharma-field-extractor
my other side: ivo.blogspot.com


Leave a Reply